
Two of the biggest names in AI just got major upgrades, and the timing couldn’t be more interesting. OpenAI has launched ChatGPT-5.5, its newest model focused on smarter reasoning, stronger coding and handling real-world tasks with less hand-holding. Meanwhile, Anthropic has rolled out Claude Opus 4.7, a model built around careful thinking, long-context performance and polished outputs for serious work.
Both promise to be the most capable version of their respective platforms so far, but they seem to be chasing slightly different visions of what an AI assistant should be: one optimized for speed, utility and execution, the other for depth, nuance and thoughtful reasoning.
Article continues below
You may like
Several prompts had clear right-or-wrong answers, allowing for direct accuracy scoring, while others were designed to test reasoning quality, assumptions and how each model thinks through more nuanced problems. Some of these prompts would challenge plenty of humans too, but that’s exactly the point. I wanted to see not just which model answers fastest, but which one answers best. Here’s what happened.
1. Multi-step probability with a twist
(Image credit: Future)
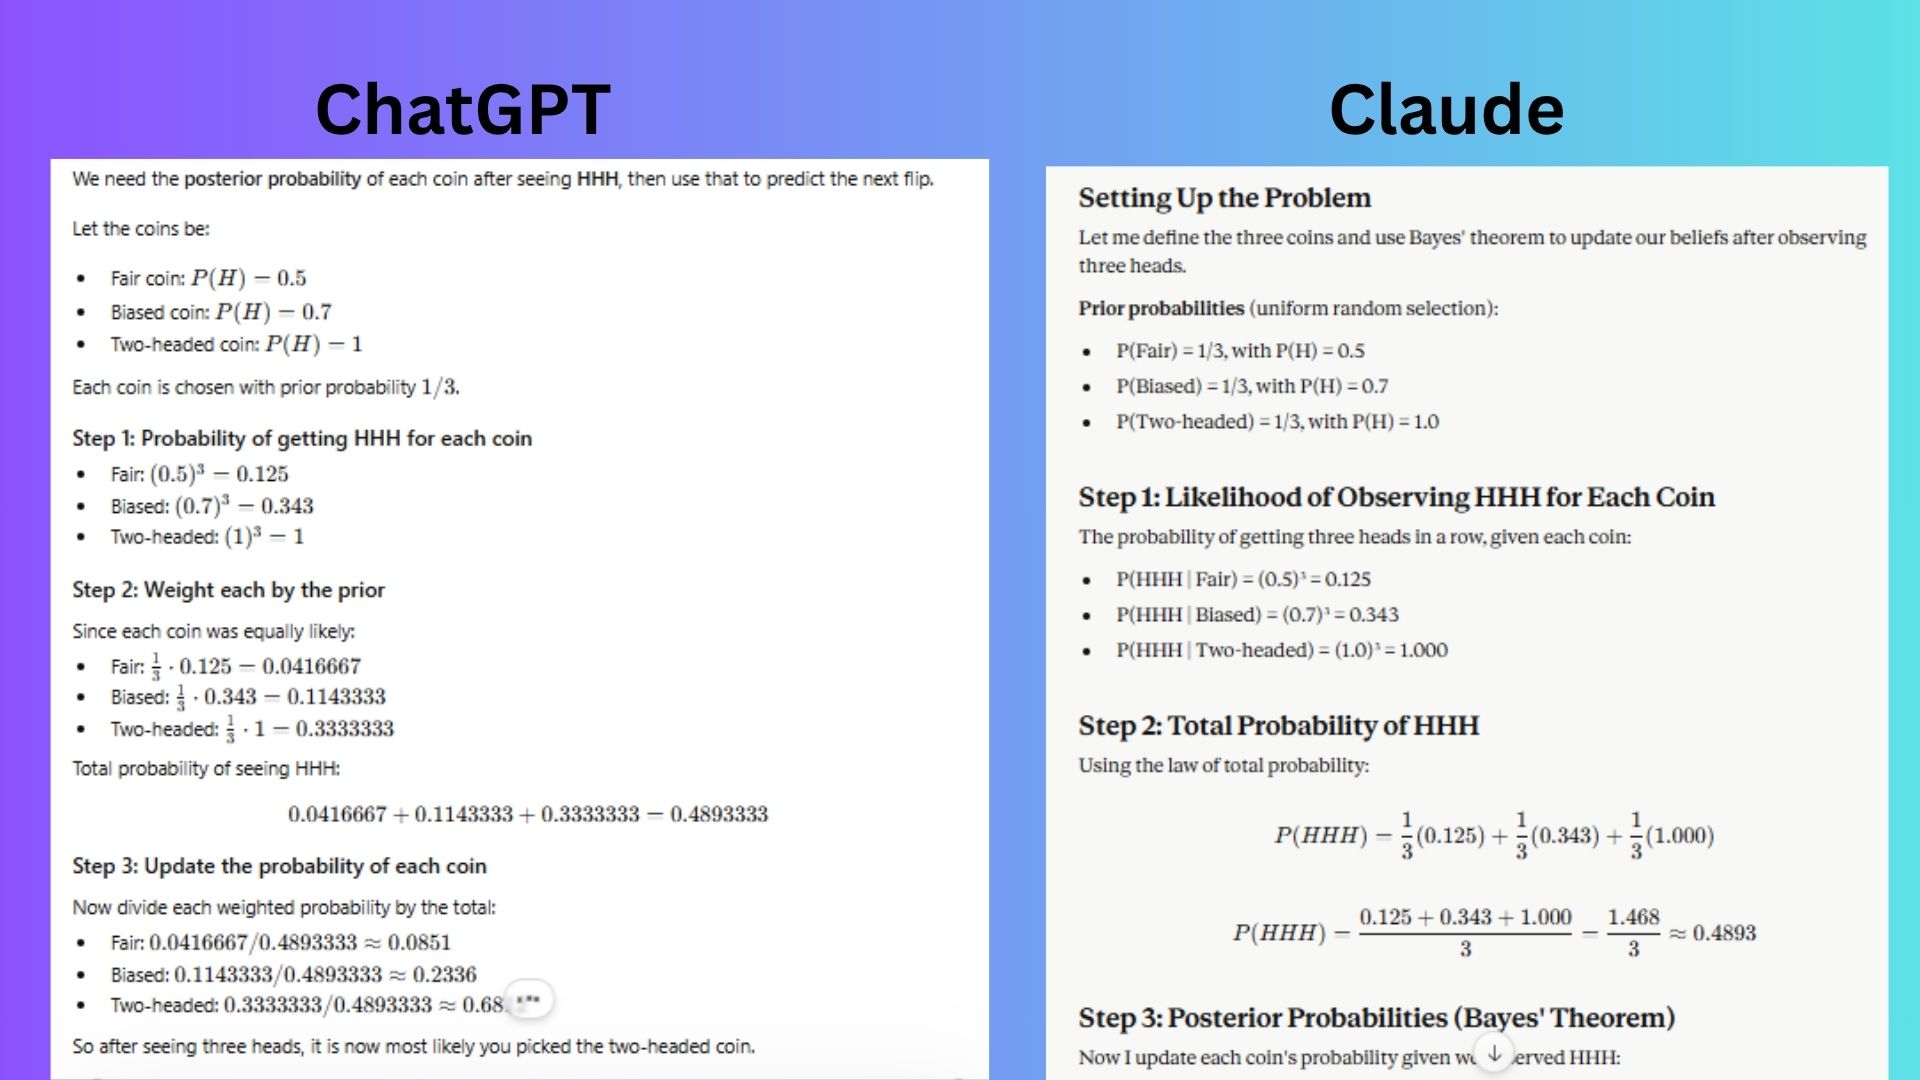
Prompt: “You have three coins: one fair, one biased with P(heads) = 0.7, and one two-headed. You pick a coin uniformly at random and flip it three times, getting heads each time. What is the probability the next flip is heads? Show your reasoning step by step.”
ChatGPT provided a very clean, structured layout that was exceptionally easy to read, with clearly labeled steps and consistent rounding.
Claude went the extra mile by providing the exact fractional derivation at the end, which confirms the mathematical rigor of the result.
Winner: Claude wins. Despite both models arriving at the correct probability of approximately 0.8874, Claude is the winner because it gave me the simplified general formula for the next flip. This internal verification demonstrates a deeper “understanding” of the shortcut in predictive probability, whereas ChatGPT simply performed the manual arithmetic.
2. Physics estimation
(Image credit: Future)
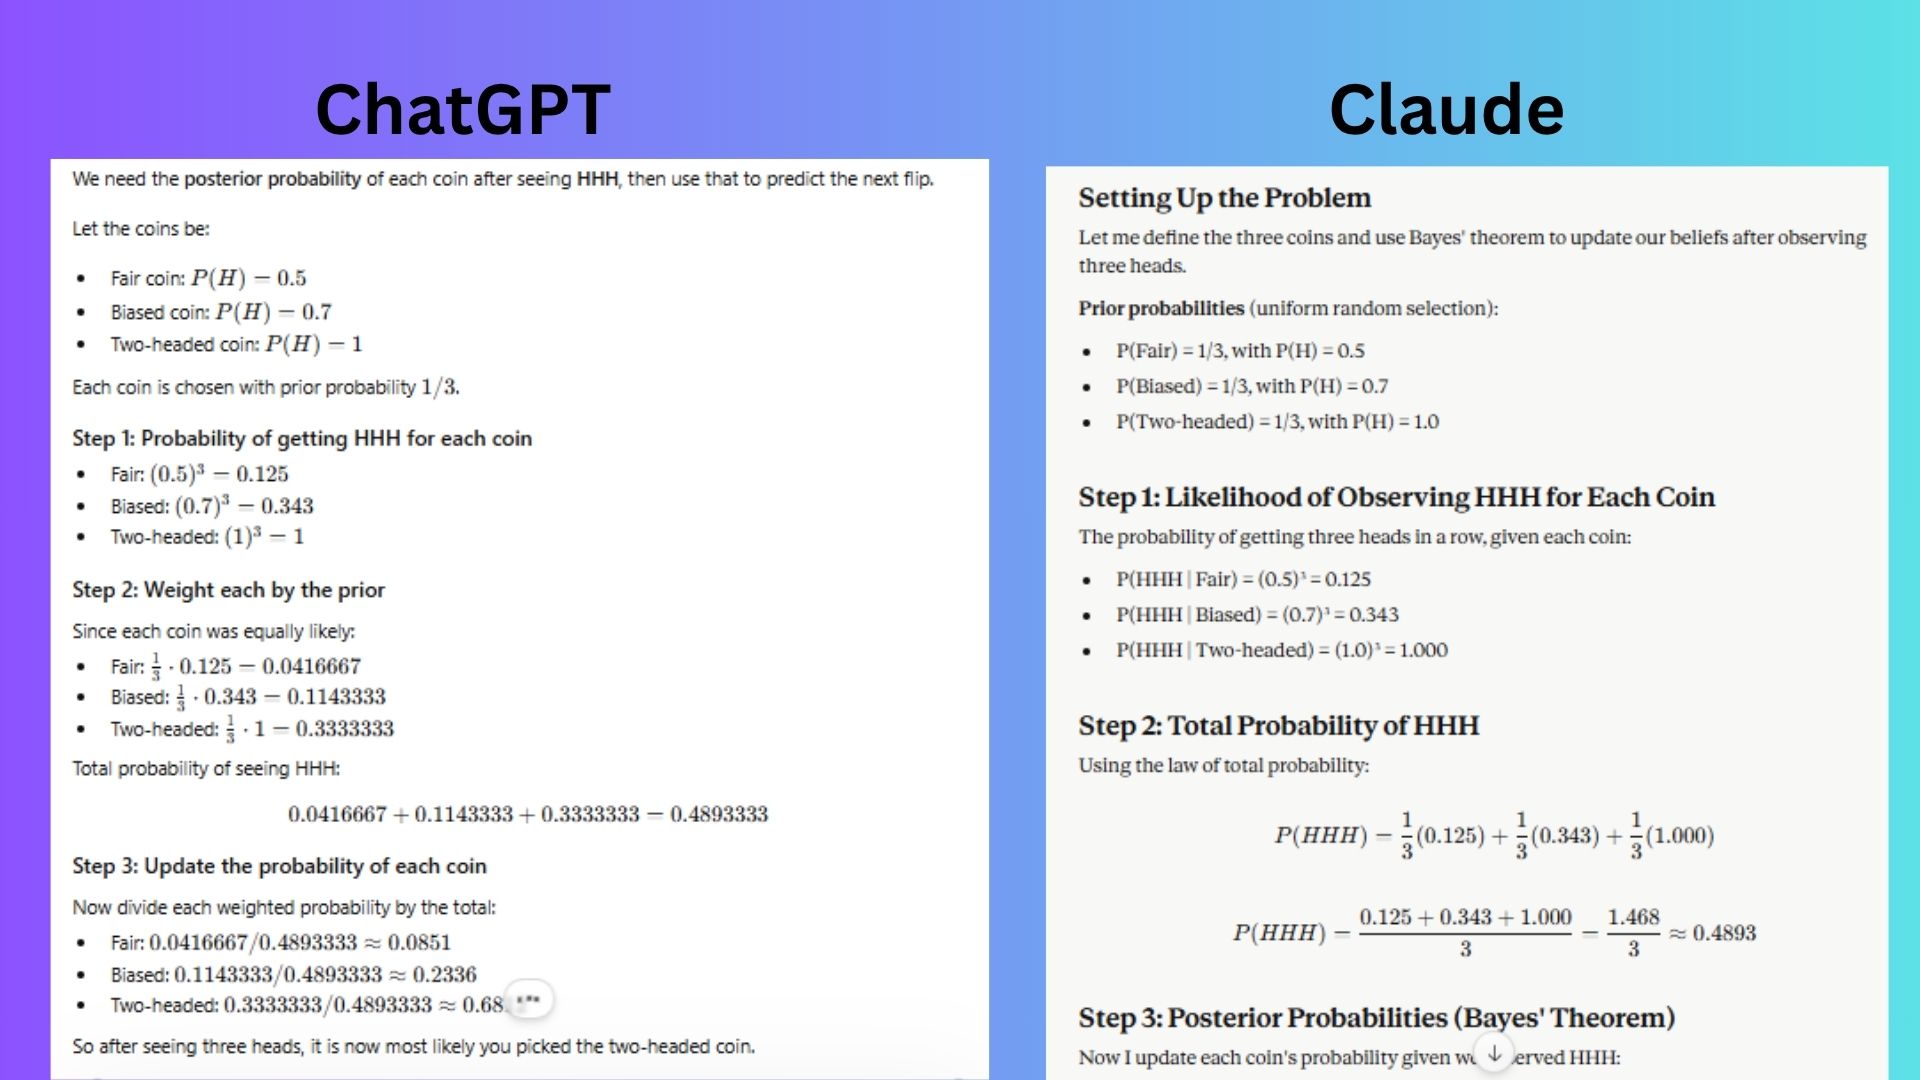
Prompt: “Estimate how much the Earth’s rotational period would change if every person on Earth (assume 8 billion people, average mass 60 kg) simultaneously jumped onto a train circling the equator at 100 km/h eastward. State your assumptions and work through the angular momentum conservation explicitly.”
ChatGPT chose a simplified value for Earth’s moment of inertia which led to a slightly higher estimate of 1.3 nanoseconds.
Claude used the more precise formula for a solid sphere and accurately calculated Earth’s moment of inertia, leading to a more grounded estimate of 1.03 nanoseconds.
What to read next
Winner: Claude wins again for itsbetter technical precision and contextual depth.
3. Proof-based math
(Image credit: Future)
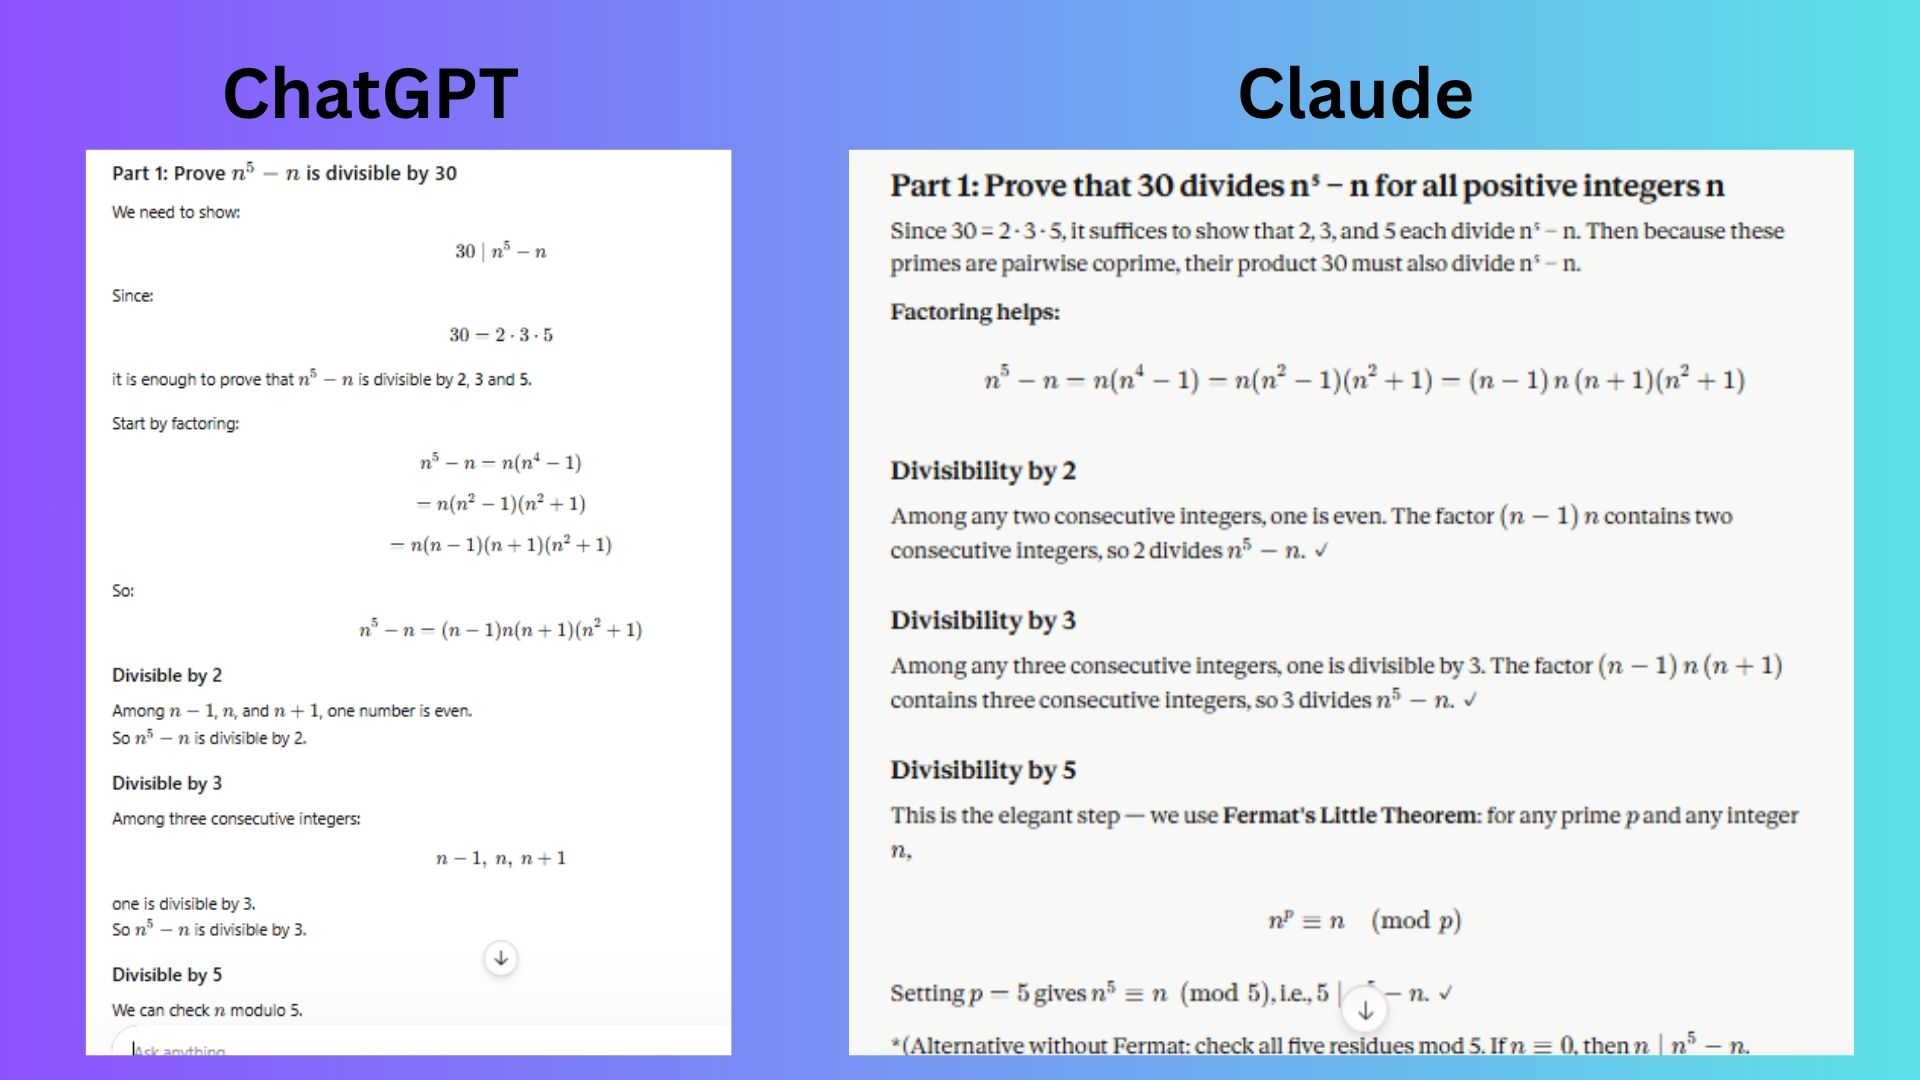
Prompt: “Prove that for any positive integer n, the number n⁵ − n is divisible by 30. Then determine whether n⁷ − n is always divisible by 42, with proof or counterexample.”
ChatGPT provided a manual modular arithmetic check, which could be helpful for readers who might not be familiar with Fermat’s Little Theorem.
Claude used Fermat’s Little Theorem more efficiently across both proofs and correctly identified the underlying mathematical structure of the problem.
Winner: Claude completesd the hat trick and is the definitive winner. While both models were mathematically accurate, Claude provided a “Beautiful Generalization” at the end.
4. Chemistry reasoning under constraints
(Image credit: Future)
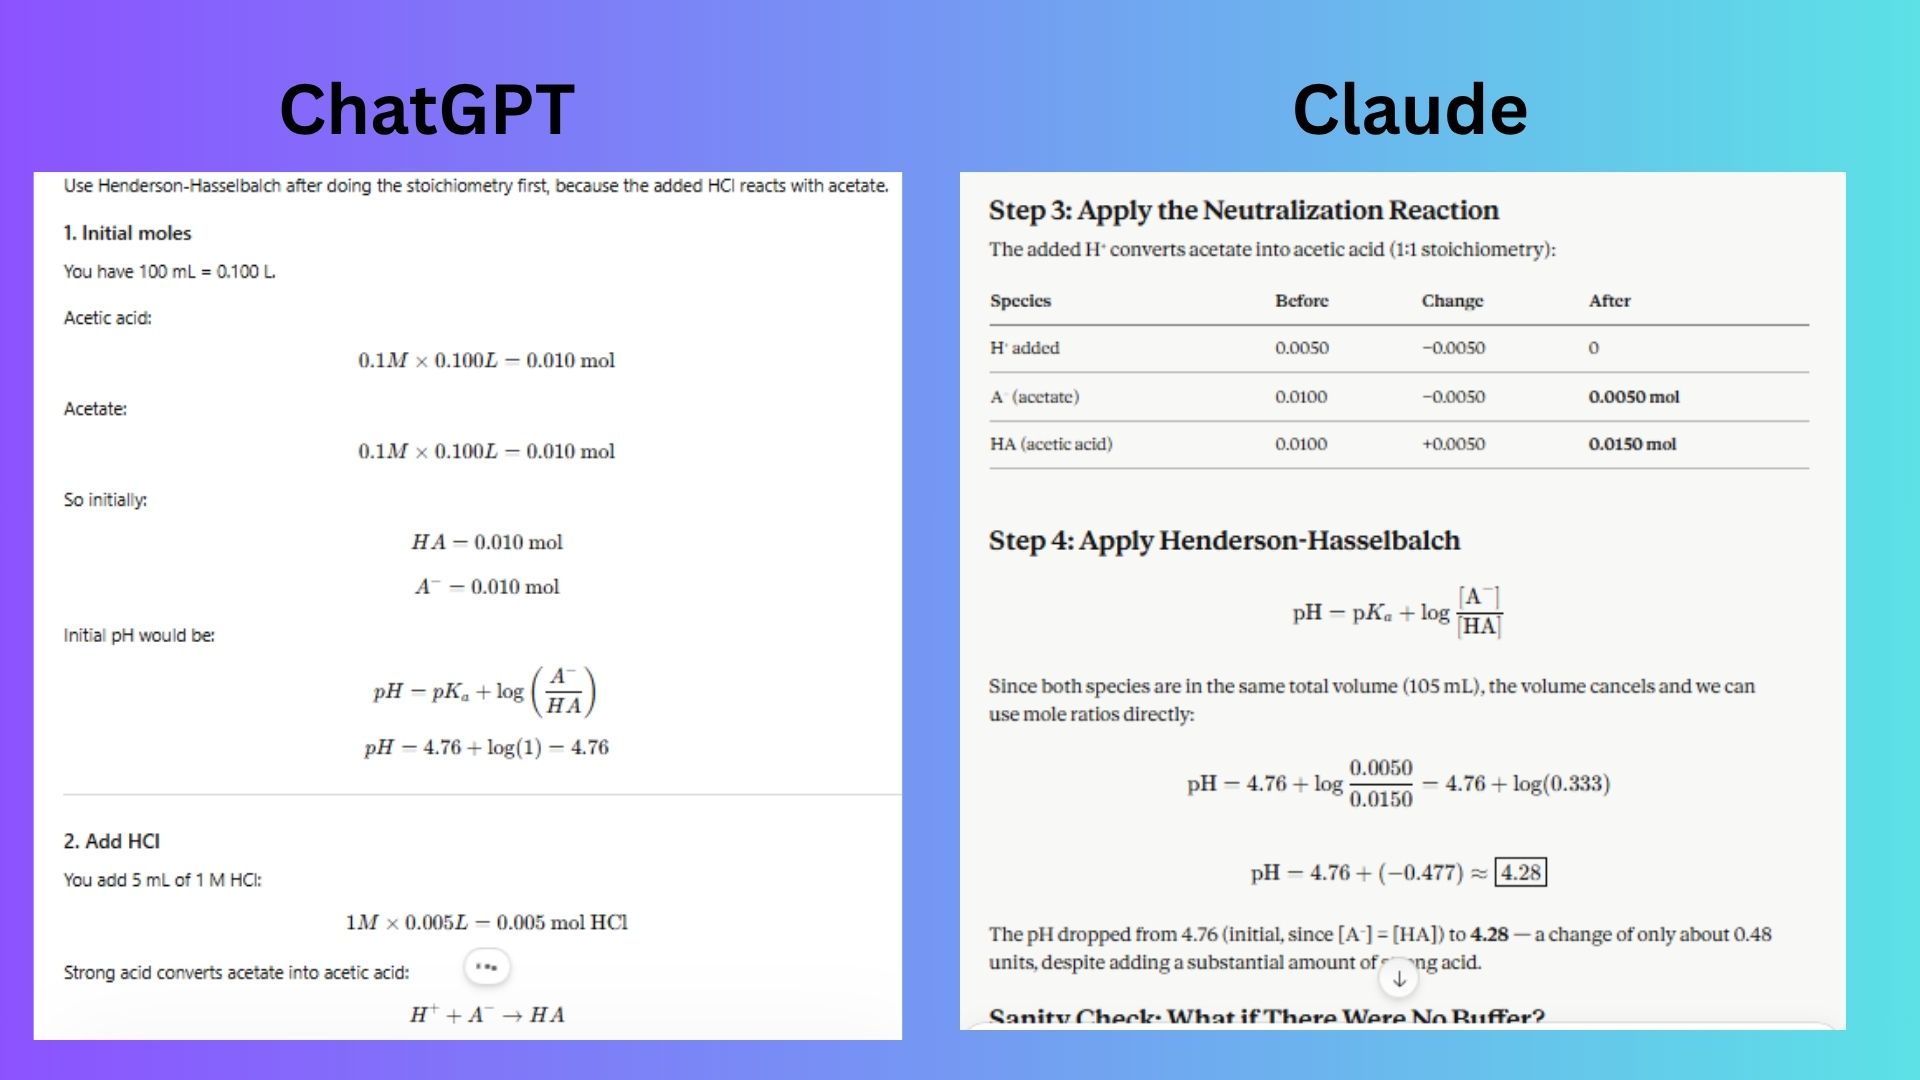
Prompt: You have 100 mL of a buffer solution containing 0.1 M acetic acid (pKa = 4.76) and 0.1 M sodium acetate. You add 5 mL of 1 M HCl. Calculate the new pH, then explain qualitatively what would happen to buffering capacity if you instead started with 0.01 M concentrations of each component, and why.
ChatGPT gave me a very direct response. The decision to explicitly calculate the “failure state” for the dilute solution makes the qualitative point very concrete.
Claude used a more formal table for the moles, which is great for chemistry students. It also provided the formal mathematical definition of buffer capacity, which added a layer of technical depth.
Winner: Claude wins. Yes, both models correctly identified that the 0.01 M buffer would be “overwhelmed,” but Claude’s explanation was more academically sound.
5. Logic puzzle requiring careful case analysis
(Image credit: Future)
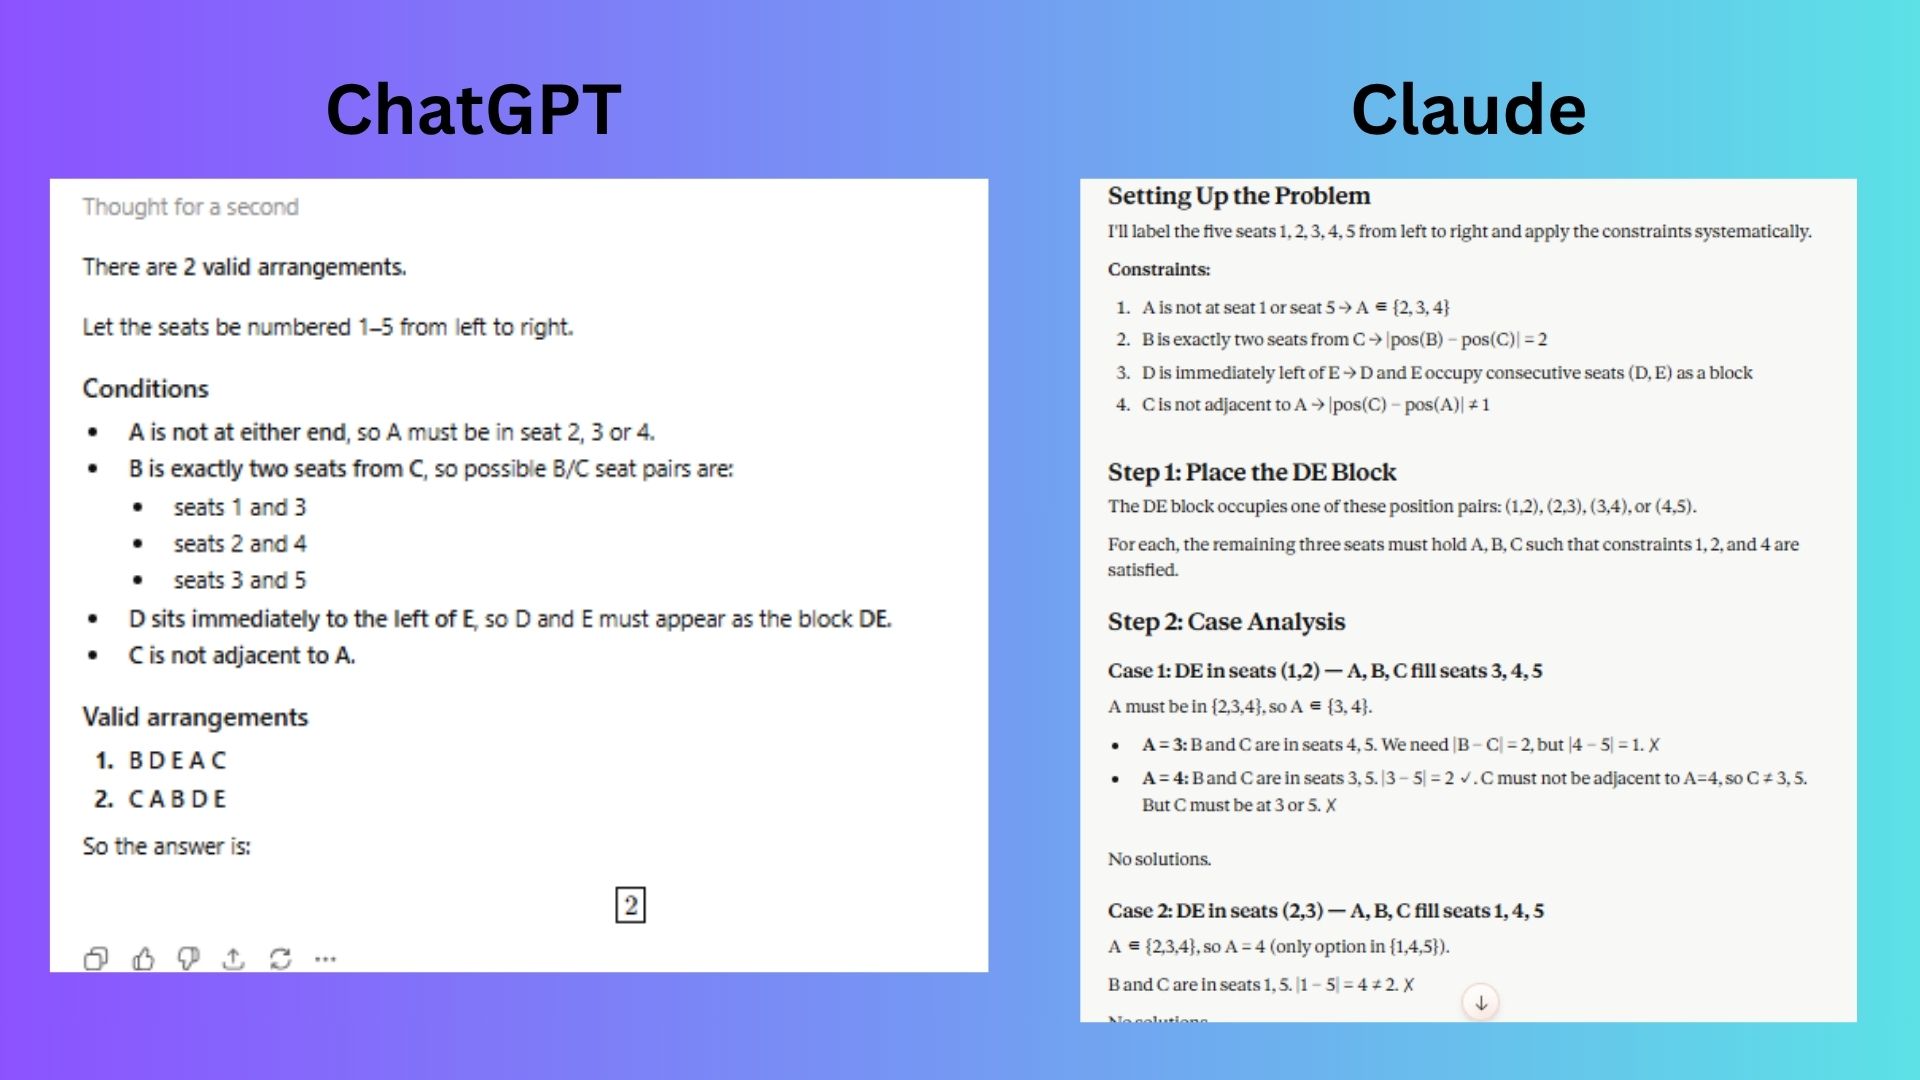
Prompt: Five people (A, B, C, D, E) sit in a row. A is not at either end. B is exactly two seats from C. D sits immediately to the left of E. C is not adjacent to A. How many valid arrangements exist? List them.
ChatGPT did exactly what I expected it to do and confidently hallucinated two solutions that violated the prompt’s constraints. A classic “reasoning collapse” move underscoring where the model prioritizes giving an answer over verifying that the answer matches the logic. Sigh. I’m really disappointed that even at GPT5-5, it’s still doing that.
Claude correctly identified that the puzzle is impossible.
Winner: Claude wins for being honest.
6. Applied calculus
Prompt: A cylindrical can must hold exactly 500 mL. The material for the top and bottom costs twice as much per square cm as the material for the sides. Find the dimensions (radius and height) that minimize total material cost. Then determine how the optimal ratio of height to diameter changes if the top/bottom cost ratio is k instead of 2.
ChatGPT gave a thorough numerical-first strategy and came up with a nearly perfect textbook response. Keyword “textbook.”
Claude provided a more rigorous mathematical treatment by including a second-derivative test to confirm the minimum, showed the exact radical forms for the dimensions and concluded with a deep intuitive summary. In other words, Claude didn’t just give a right answer, it showed how it got there so I would fully fully understand.
Winner: Claude wins again but by a narrower margin this time. ChatGPT’s answer was flawless, but Claude’s “interpretation” section made its response so much more thorough for giving the “why” behind the answer.
7. Scientific reasoning trap
Prompt: A study finds that people who drink coffee live, on average, 2 years longer than non-drinkers (p < 0.001, n = 50,000). A journalist concludes coffee extends lifespan. Identify at least four distinct methodological or inferential problems with this conclusion, and design a study that would more reliably establish causation. Be specific about what each proposed design controls for.
ChatGPT spotted the main problems researchers worry about in studies like this, such as whether another factor is influencing the results or whether the cause and effect are being mixed up. It also suggested running a randomized trial, which is usually a stronger way to test whether something really causes an outcome.
Claude not only gave a better and more thorough response, but elevated the answer to a professional/research level.
Winner: Claude wins another round with its thorough responses highlighting once again how it handles multidimensional reasoning better than ChatGPT’s linear approach.
Overall Winner: Claude
The results of this faceoff surprised me. Not only did I somehow manage to keep up with advanced math I haven’t touched since college — seriously, if these AIs get any smarter, I may need to phone a former professor — but ChatGPT didn’t win a single round.
Going into this, I expected a back-and-forth battle. Instead, I saw two models heading in completely different directions. ChatGPT-5.5 is clearly built for the “utility” user with it’s speed and ability to follow a standard template. But when the truth matters (literally, always) like the impossible logic puzzle, it fell back on “pleasing” me with a hallucination rather than admitting defeat.
Claude Opus 4.7 feels like it has been built with a “measure twice, cut once” philosophy. Its sweep in all seven rounds proves it not only will get the answers right, but it will also provide the reasoning behind it. Whether it was adding a “Sanity Check” to a physics problem or identifying the underlying theorem in a math proof, Claude provided a level of academic integrity that ChatGPT simply couldn’t match.
The most obvious takeaway here isn’t just that Claude won, but how easily it did so. In the world of high-level reasoning, ChatGPT has some serious catching up to do.
Follow Tom’s Guide on Google News and add us as a preferred source to get our up-to-date news, analysis, and reviews in your feeds.
More from Tom’s Guide