Follow us
Add us as a preferred source on Google
Newsletter
Subscribe to our newsletter
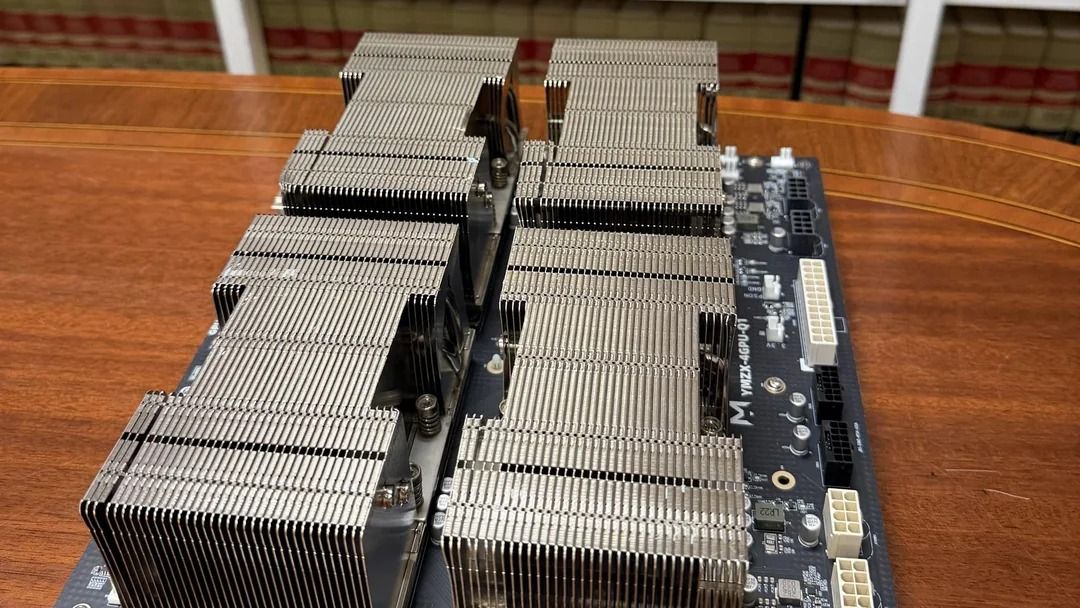
A lawyer posted on Reddit about their private AI server built from eight used 2018-era Nvidia Tesla V100 data center GPUs so case files never have to leave the office. With two 4-card SXM2 NVLink boards, four PEX switches, and SlimSAS cables everywhere — plus one burnt power connector — the builder now runs the open DeepSeek V4.1 Flash model with every expert in GPU memory, at up to 215 tokens per second. The four-GPU boards cost about $2,400 apiece when the builder bought them.
Lawyer’s V100 homelab, update: two 4-card SXM2 NVLink boards, four PEX switches, SlimSAS everywhere, one burnt power connector, and a 250 GB model running entirely in VRAM at 200+ tok/s from r/homelab
Latest Videos FromTom’s Hardware
You may like
Swipe to scroll horizontally
DeepSeek V4.1 Flash on eight Tesla V100s, by prompt length
Prompt length
Wait for first token
Code (tokens/s)
Legal writing (tokens/s)
1K tokens
1.2 seconds
215
118
32K tokens
17.2 seconds
200
117
128K tokens
59.2 seconds
183
111
256K tokens
118.7 seconds
160
103
What to read next