
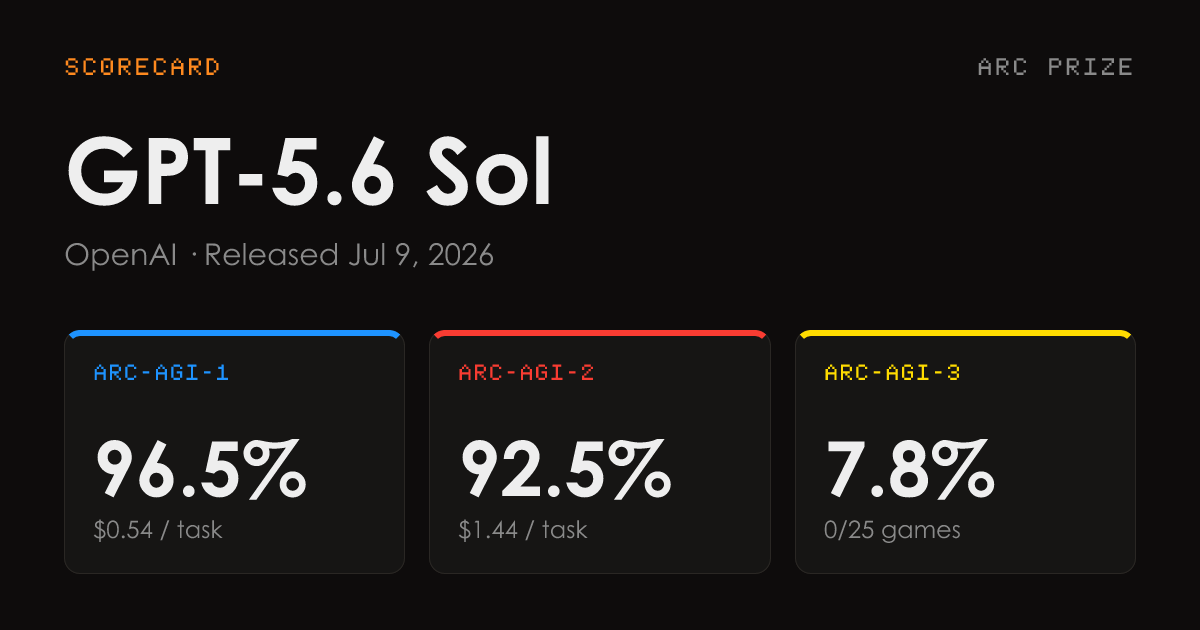

OpenAI·Jul 9, 2026·3 models·15 reasoning variants
GPT-5.6 Sol is the standout model of the GPT-5.6 family. Sol at max reasoning effort is the only performant model (as of July 2026) averaging 13.33% on Public and 7.78% on Semi-Private. It is the first model to win an ARC-AGI-3 public game (ft09, 87%). Sol is able to read an unfamiliar scene correctly and in the game’s own vocabulary. It treats a failed hypothesis as a reason to re-plan rather than thrash. Most agent failures are upstream of the code they write or the action they take. Sol is able to perform on ARC-AGI not because it executes better, but because it correctly orients itself in a new environment first.
ARC-AGI 3 leaderboard
GPT-5.6 SolGPT-5.6 TerraGPT-5.6 Luna
ARC-AGI-1ARC-AGI-2ARC-AGI-3
Verified scoresModelVariantARC-AGI-1ARC-AGI-2ARC-AGI-3SolMax
96.5%
92.5%
7.8%
Extra High
97.5%
90.0%
7.0%
High
97.0%
85.4%
2.1%
Medium
92.5%
67.1%
1.1%
Low
74.5%
42.5%
0.3%
TerraMax
96.5%
83.9%
0.8%
Extra High
94.0%
74.2%
0.7%
High
92.0%
67.1%
0.5%
Medium
77.0%
37.5%
0.1%
Low
60.2%
18.8%
0.0%
LunaMax
88.0%
59.5%
0.2%
Extra High
87.7%
47.6%
0.0%
High
76.5%
29.3%
0.1%
Medium
56.5%
7.4%
0.2%
Low
34.2%
5.1%
0.2%
Tasks & environments
Pass/fail per reasoning level across each benchmark. Hardest tasks (fewest levels solving) are listed first.
ModelGPT-5.6 SolGPT-5.6 TerraGPT-5.6 Luna
ARC-AGI-3 Public Demo25 environments
ARC-AGI-2 Public Eval120 tasks
ARC-AGI-1 Public Eval400 tasks